Team
You'll talk to the people
who do the work.
Small by design. Everyone here is senior, and the person you scope with is the person who writes the code, signs off on the architecture, and answers when something breaks.
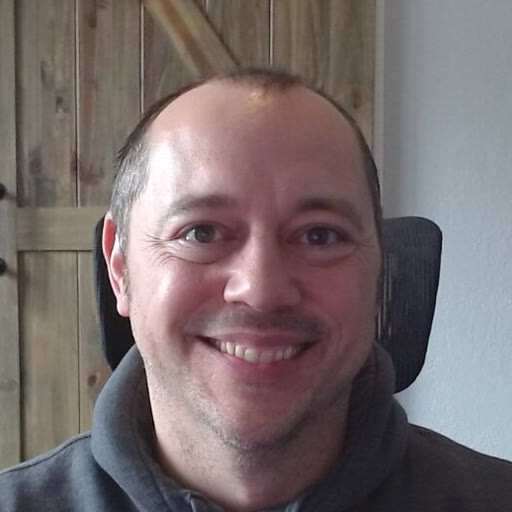
Matt founded 419 Technology and runs the build side of every engagement: architecture, infrastructure, and the call on which systems live or die. Twenty-plus years writing production code, most of it in the seat where "it works on my machine" is not an acceptable answer. He holds eleven current certifications across Kubernetes, Google Cloud, AWS, and Microsoft, including Kubestronaut (all five CNCF Kubernetes certifications), GCP Professional Cloud Architect, and AWS DevOps Engineer Professional.
- Applied AI & LLM systems · production pipelines and agentic workflows across Anthropic, OpenAI, and Gemini: model routing, evals, cost governance, and the guardrails that keep AI features shippable. n8n and custom Python and Go services when the workflow needs to run unattended.
- Cloud & infrastructure as code · GCP, AWS, and Azure in production. Datacenter-to-cloud migrations, Kubernetes, Terraform, Helm, and ArgoCD-driven GitOps as the default way systems get built and changed.
- Data & databases · PostgreSQL, MySQL, SQL Server, Redis, and BigQuery: schema design, performance tuning, major-version upgrades, and zero-data-loss migrations at production scale.
- DevOps, security & observability · CI/CD pipelines, Prometheus, Grafana, and Loki; WAF, TLS, and edge hardening; full-codebase security reviews of legacy platforms. If it runs, it gets monitored; if it breaks, it pages.
Recent engagements
- Moved a 20-year-old, revenue-critical web platform out of a managed datacenter and onto Google Cloud with no data loss, then cut the monthly bill by a third and kept it there with a standing cost-analysis service.
- Built the go-live observability stack for that platform: Prometheus, Grafana, Loki, and Alertmanager wired to Slack paging, with a dead-man switch so silence is an alert too.
- Ran major-version production database upgrades (MySQL 5.7 to 8.4) across three environments on AWS for an education-technology platform handling regulated student data.
- Got an AI forecasting platform's LLM ensemble to 4-7x the throughput on the same infrastructure by fixing the pipeline instead of buying more compute.
- Designs, builds, and operates 419's own products end to end, including CurlyFry.ai, a production AI SaaS for engineering managers.
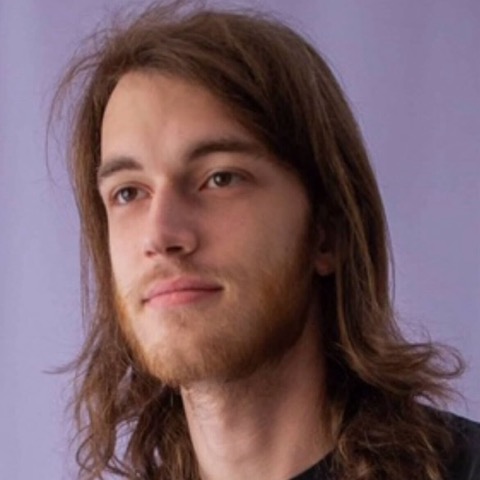
Nick
Senior Engineer
Nick works the infrastructure and reliability side of 419 engagements: Kubernetes, infrastructure as code, and the systems that keep production up when something fails. Recent work includes caching and data-layer builds on GCP for a production AI platform.
- AI cost analysis & governance · tooling to track and analyze LLM/AI spend across production pipelines, surfacing cost drivers before they hit the bill.
- Kubernetes & infrastructure as code · production Kubernetes clusters and IaC (Terraform, GitOps) as the default way systems get built and changed.
- Reliability & failover architecture · alert-driven automated failover between live production environments, so systems stay up when something breaks.
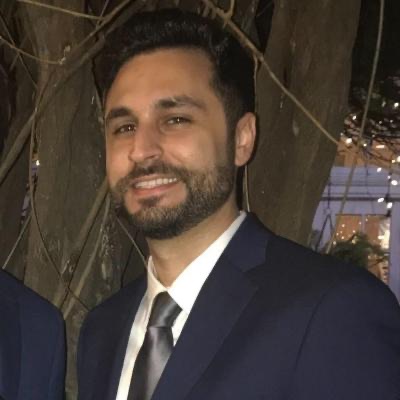
Ivan
Senior DevOps & Platform Engineer
Ivan works the platform and automation side of 419 engagements: Kubernetes, infrastructure as code, and the observability that catches a problem before the customer does. Much of it in enterprise and regulated environments, where systems have to stay consistent and auditable as they scale.
- Production Kubernetes · highly available, multi-cluster, multi-environment architectures supporting dozens to hundreds of client workloads.
- Infrastructure as code & GitOps · Terraform that stays modular across accounts and environments, delivered through ArgoCD: PR-based change control, promotion gates, and full audit trails.
- Observability & SLOs · Prometheus and Grafana wired for signal, not noise: service level objectives that reflect user impact, dashboards someone actually reads at 2am, and alerting tuned to page a human only when a human is needed.
- Automation & hardening · automation that cuts operational overhead instead of adding to it, plus cluster-level security hardening. Toil that shows up twice becomes a pipeline the third time.
Something broken, or something to build? Start a conversation →